There is a lot of confident writing about how AI crawlers behave on slow sites. Most of it is not sourced, because the sources mostly don't exist: compared to Google, the AI vendors publish very little about the mechanics of their crawlers.
This article sticks to what the vendors actually document, and is explicit about the gaps. Where something isn't documented, we say so rather than filling it in.
The crawlers, and what each one is for
The first thing to get right is that "AI crawler" covers three different jobs, and they have very different latency profiles.
| User-agent | Vendor | Purpose (as documented) |
|---|---|---|
GPTBot |
OpenAI | Crawls content that may be used to train foundation models |
OAI-SearchBot |
OpenAI | Surfaces websites in ChatGPT's search results |
ChatGPT-User |
OpenAI | Visits a page when a user asks ChatGPT or a custom GPT a question |
ClaudeBot |
Anthropic | Collects web content for model training and development |
Claude-SearchBot |
Anthropic | Indexes content to improve search result quality |
Claude-User |
Anthropic | Retrieves sites when users ask Claude questions |
PerplexityBot |
Perplexity | Surfaces and links websites in Perplexity search results |
Perplexity-User |
Perplexity | Fetches pages when a user's question requires them |
Sources: OpenAI's bots documentation, Anthropic's crawler article, Perplexity's bots guide.
The split that matters for performance is scheduled crawling (GPTBot, ClaudeBot, OAI-SearchBot, Claude-SearchBot, PerplexityBot) versus user-initiated fetching (ChatGPT-User, Claude-User, Perplexity-User). We come back to this below, because it is where a cold cache does real damage.
What the vendors do not document
Two things are conspicuously absent from all three vendors' documentation, and both are exactly what you'd want to know:
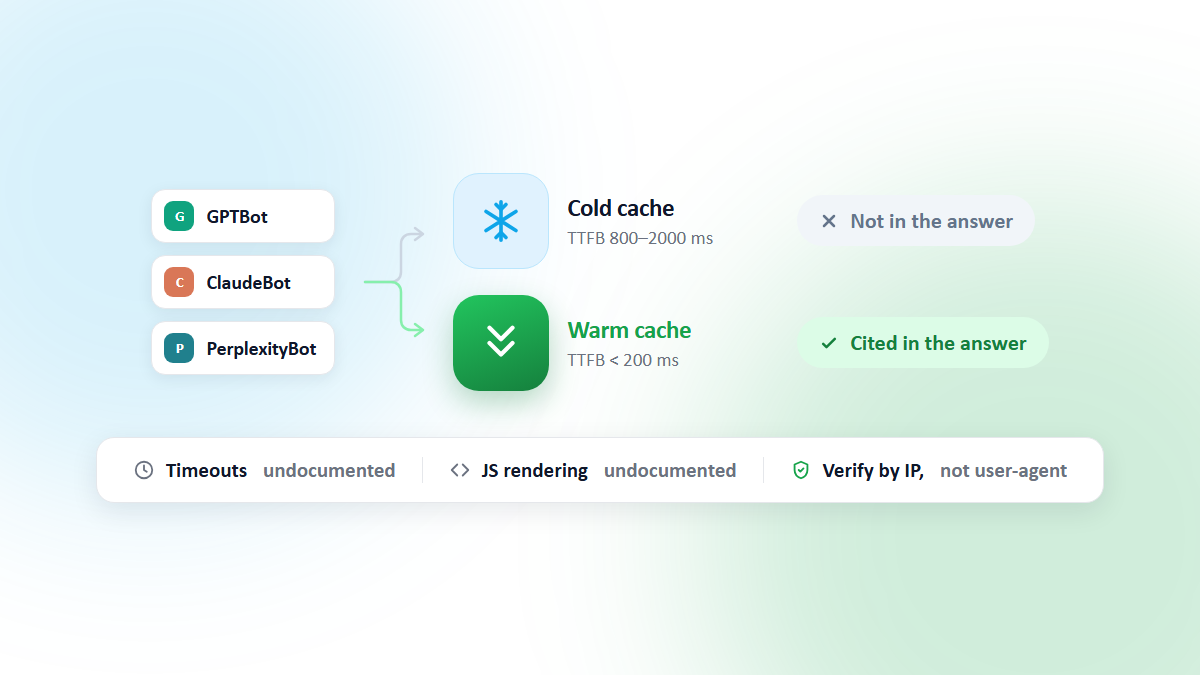
1. Timeouts. None of OpenAI, Anthropic or Perplexity publishes a request timeout, a retry policy, or any statement about how much slowness their crawlers tolerate before giving up. If you have read a specific number somewhere, it did not come from the vendor.
2. JavaScript rendering. None of the three states whether their crawlers execute JavaScript. This is a real gap: Google, by contrast, is explicit that it can process content inside JavaScript as long as it isn't blocked, and has documented its render pipeline for years.
The honest engineering conclusion from an undocumented behaviour is not "they don't render JS": it's don't depend on it. If your content only exists after hydration, you are betting your AI visibility on an undocumented capability from three different vendors, each free to change it without notice. Server-rendered HTML removes the bet entirely.
The same logic applies to slowness. Since no vendor commits to waiting, the safe assumption is that patience is short and unadvertised. A page that answers in 150 ms is a non-issue; a page that answers in 3 seconds because the cache just got flushed is a gamble against a rule nobody has published.
What the vendors won't tell you, independent testing can partly fill in. The next section covers what one such test actually measured.
What independent testing found
The vendors' silence doesn't make the behaviour unknowable, it just means you have to go and measure it. In January 2026, RESONEO published a test that did exactly that: one page carrying 15 different content-injection methods (static HTML, <noscript>, inline JS, delayed JS, fetch(), Shadow DOM, iframes, <template>), each holding a unique sentinel string. They then asked each assistant to fetch the page and report which sentinels it could see, logging headers and timing server-side.
Note the scope: the test covers user-mode fetchers only, and explicitly excludes the indexing crawlers (GPTBot, ClaudeBot). That is the same split that matters for latency.
| Assistant | User-agent observed | JavaScript | Waits for content |
|---|---|---|---|
| ChatGPT | ChatGPT-User |
No | n/a |
| Claude | Claude-User |
No | n/a |
| Gemini | Google |
No | n/a |
| Perplexity | Perplexity-User |
No (see below) | n/a |
| Grok | stealth, multi-IP | Yes, incl. fetch() |
~2 s |
| DeepSeek | stealth Firefox | Yes, incl. fetch() |
~1 s |
| Bing Copilot | stealth Chrome | Yes, incl. Shadow DOM and iframes | ~53 ms |
| Google AI Mode | none | Does not fetch URLs at all | n/a |
Four findings worth acting on:
- ChatGPT, Claude and Gemini read static HTML only. They pick up
<noscript>and<template>content, but nothing produced by JavaScript. This is a measurement rather than a vendor commitment, so it can change without notice, but it is the best evidence available and it points the same way as the cautious assumption. - The JS-capable ones have very little patience. Grok waits roughly 2 s, DeepSeek roughly 1 s, and Bing Copilot around 53 ms. These are waits for content to appear rather than HTTP timeouts, but the direction is unambiguous: a page still assembling itself after a second has already lost.
Perplexity-Userarrived with empty HTTP headers and failed to decode the compressed response, seeing nothing at all. If Perplexity matters to you, check how your origin and CDN handle a request with an emptyAccept-Encoding.- Google AI Mode never fetches the URL. It answers from the Search index, so the lever there is ordinary indexing and crawl budget, not live fetch speed, which loops straight back to Googlebot's crawl rate.
Caveats, stated plainly: this is one test page from one agency, with no published sample size or collection period, and crawler behaviour changes without notice. Treat it as a strong signal rather than a specification, re-test before betting on it, and keep the structural conclusion either way: content that only exists after JavaScript is content most AI assistants do not see.
What is documented about crawl rate
A little, and it is worth knowing:
- Anthropic states it aims for "minimal disruption by being thoughtful about how quickly we crawl the same domains", honours
robots.txt, and supports the non-standardCrawl-delaydirective. - OpenAI and Perplexity both document that
robots.txtchanges take up to 24 hours to take effect. - Perplexity notes that
Perplexity-Usergenerally ignoresrobots.txt, on the grounds that a human initiated the request.
What none of them documents is an equivalent of Google's crawl-rate feedback loop, where a slow or erroring server measurably reduces how much gets crawled. With Google you can reason about the mechanism. With the AI crawlers you cannot, which is another argument for not giving them slow pages in the first place.
Where a cold cache actually costs you: the live fetch
Scheduled crawling is fairly forgiving. If GPTBot hits a cold page today, it will likely be back.
The user-initiated agents are a different situation. ChatGPT-User, Claude-User and Perplexity-User fetch your page while someone is waiting for an answer. There is no retry queue and no second pass: the latency lands inside a live conversation, and a fetch that is too slow is simply a page that didn't make it into the answer.
That is the GEO-specific version of the cold-cache problem. The traditional SEO framing (slow page → weaker signal → lower ranking over weeks) gets replaced by something much more immediate: slow page → not in this answer.
And unlike a crawler, these fetches arrive unpredictably, driven by whatever people happen to ask. You cannot schedule around them. The only defence is a cache that is already warm when they show up.
Identifying AI crawler traffic in your logs
User-agent strings are trivially spoofed, so what you should do with them depends on the question you're asking.
For measuring volumes and cache hit ratio, classifying on the user-agent is fine. Nobody gains anything by faking a GPTBot header to distort your hit-ratio chart, so misattribution is noise rather than risk.
For anything where you trust the identity (allowing, blocking, rate-limiting, or serving different content), verify against the ranges each vendor publishes as JSON:
- OpenAI:
openai.com/gptbot.json,openai.com/searchbot.json,openai.com/chatgpt-user.json - Anthropic:
claude.com/crawling/bots.json - Perplexity:
perplexity.com/perplexitybot.json,perplexity.com/perplexity-user.json
A practical measurement workflow:
- Pull your CDN's request logs or analytics, keeping the cache status on each row.
- Classify each request into a bot bucket.
- Group by bot and by cache status (
HIT/MISS/EXPIRED) and compute a hit ratio per bot. - Cross-reference the
MISSrows against your deploy and purge times.
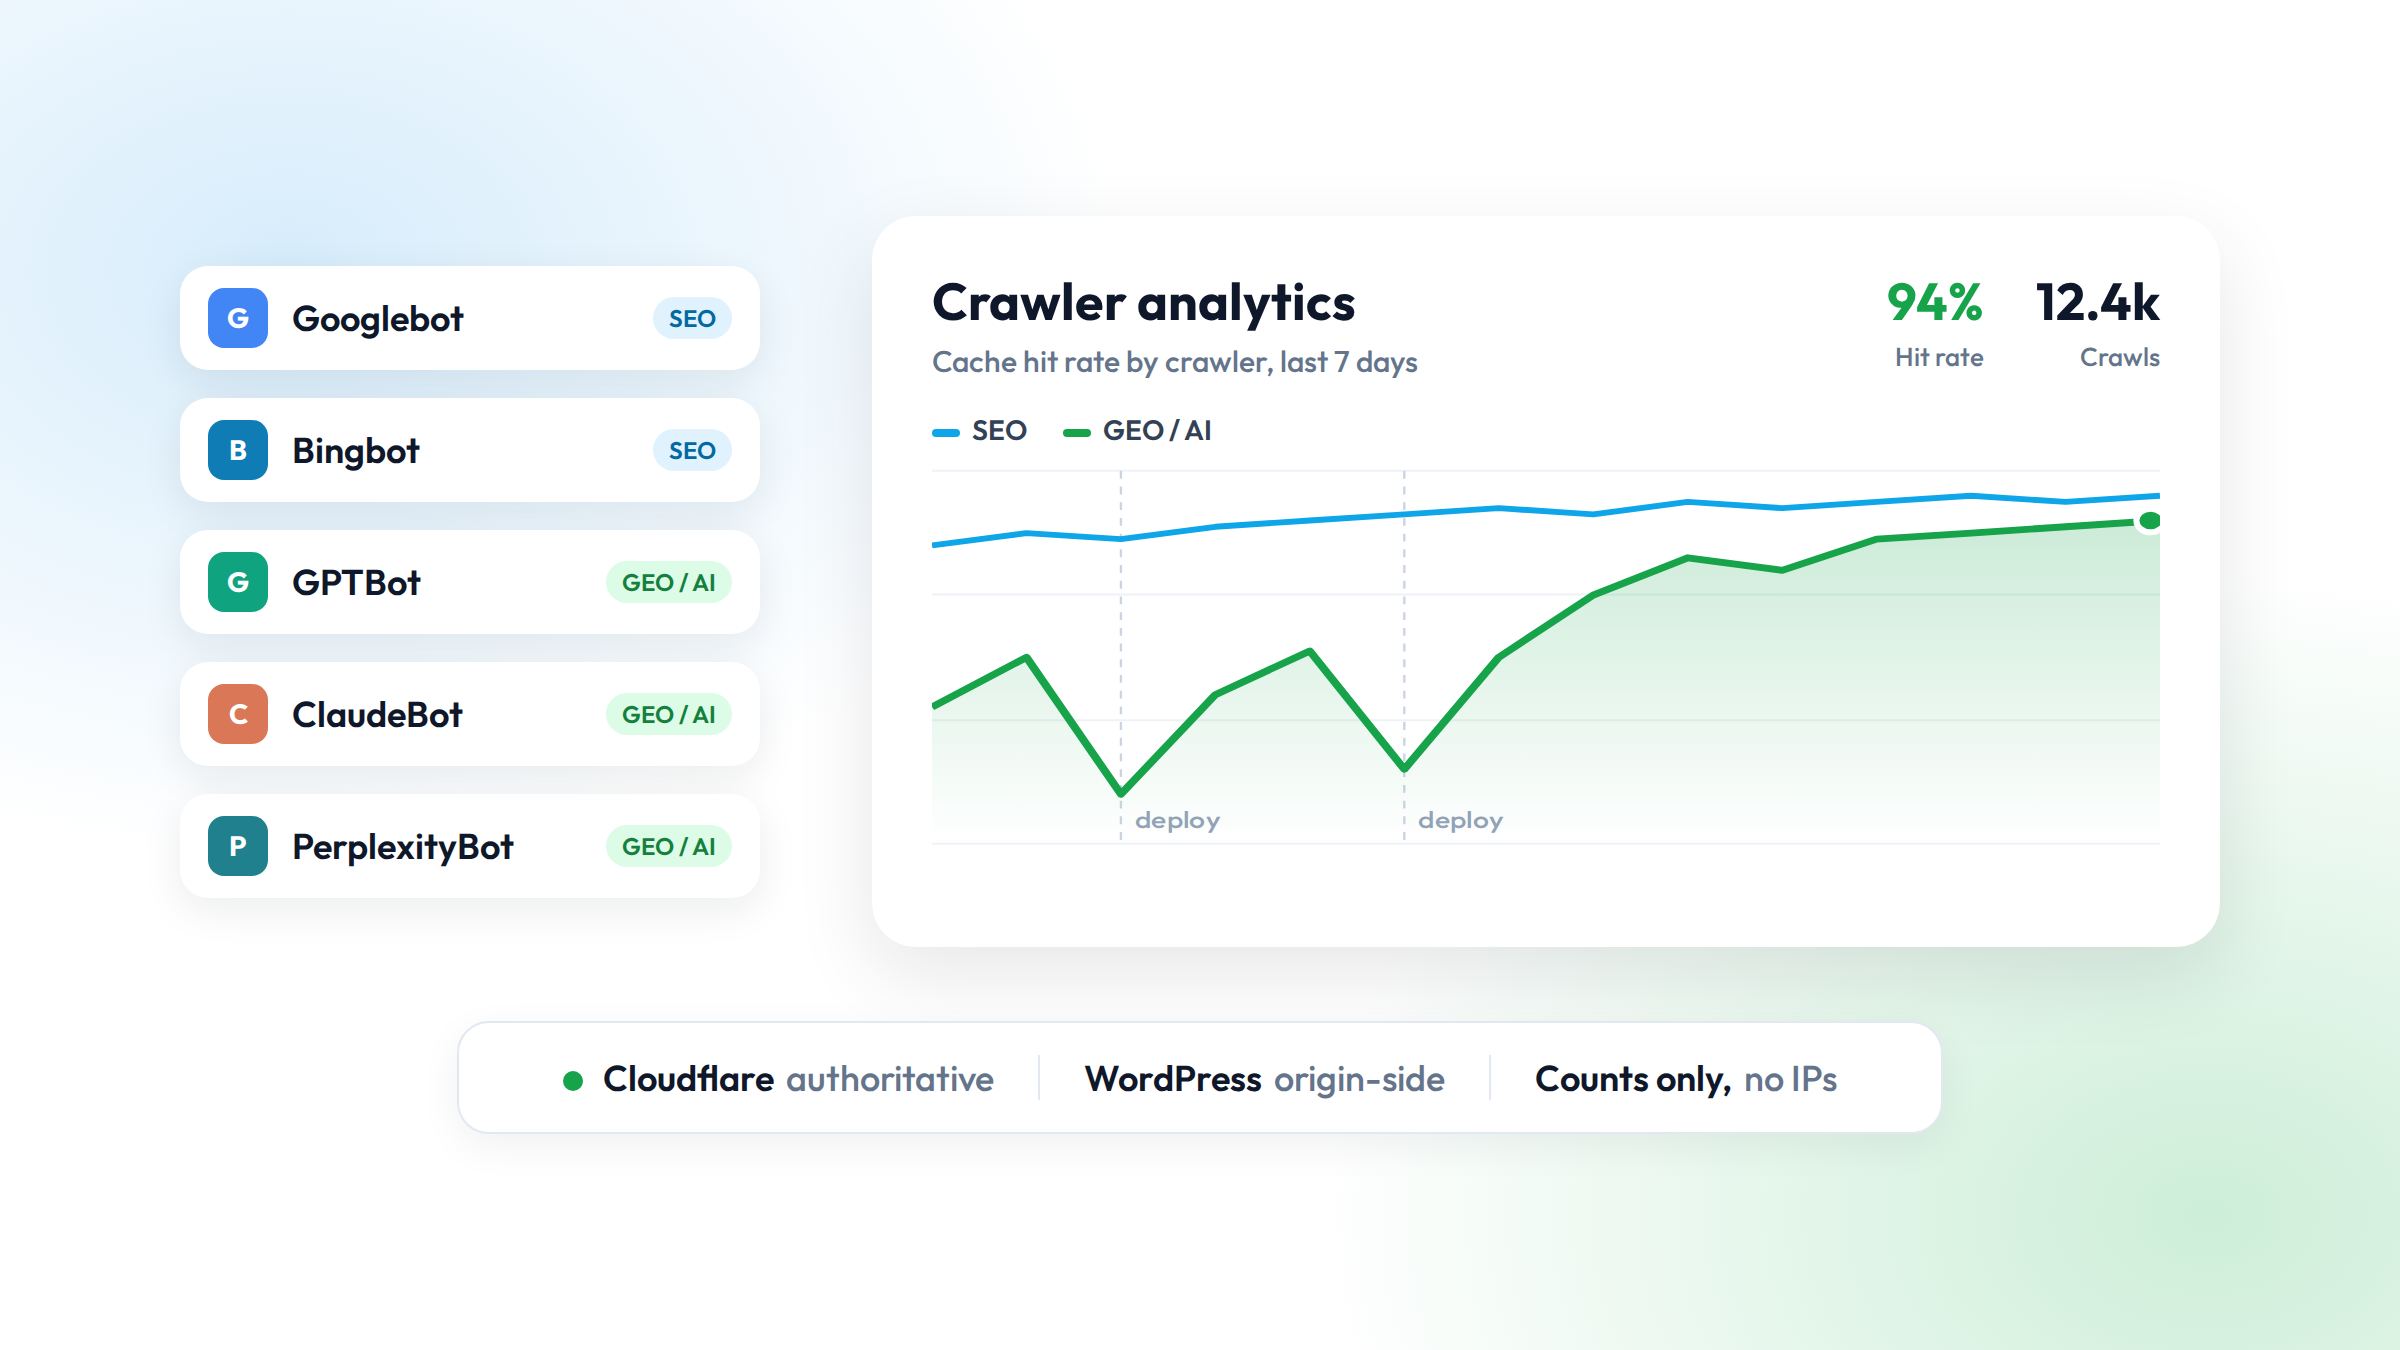
If the AI-crawler hit ratio is visibly worse than your overall hit ratio, the usual cause is timing: these agents arrive on a schedule you don't control, so they disproportionately land in the window right after a purge, before organic traffic has rebuilt the cache. Warming closes that window.
Note that Anthropic itself cautions that blocking by IP "may not work correctly" and recommends robots.txt instead. That caveat is about blocking, not about observability.
A word on your WAF
Because bot user-agents are spoofed so often, bot-management products are aggressive about requests that claim to be a known crawler from an IP that doesn't check out. That is the correct behaviour, and it has a side effect worth knowing: if you warm your cache using a GPTBot or ClaudeBot user-agent string from your own infrastructure, your WAF may challenge or drop those requests, and the cache stays cold while your warming dashboard reports success.
Whitelist your warming IPs before you warm with bot user-agents, and check first whether your cache key even varies on user-agent, because if it doesn't, warming a single variant covers all of them.
What to actually do
- Serve the content in the HTML. No vendor documents JavaScript rendering, and independent testing found that ChatGPT, Claude and Gemini don't execute it. Don't bet on it.
- Keep TTFB low all the time, not on average. User-initiated fetches arrive at random, including right after a purge.
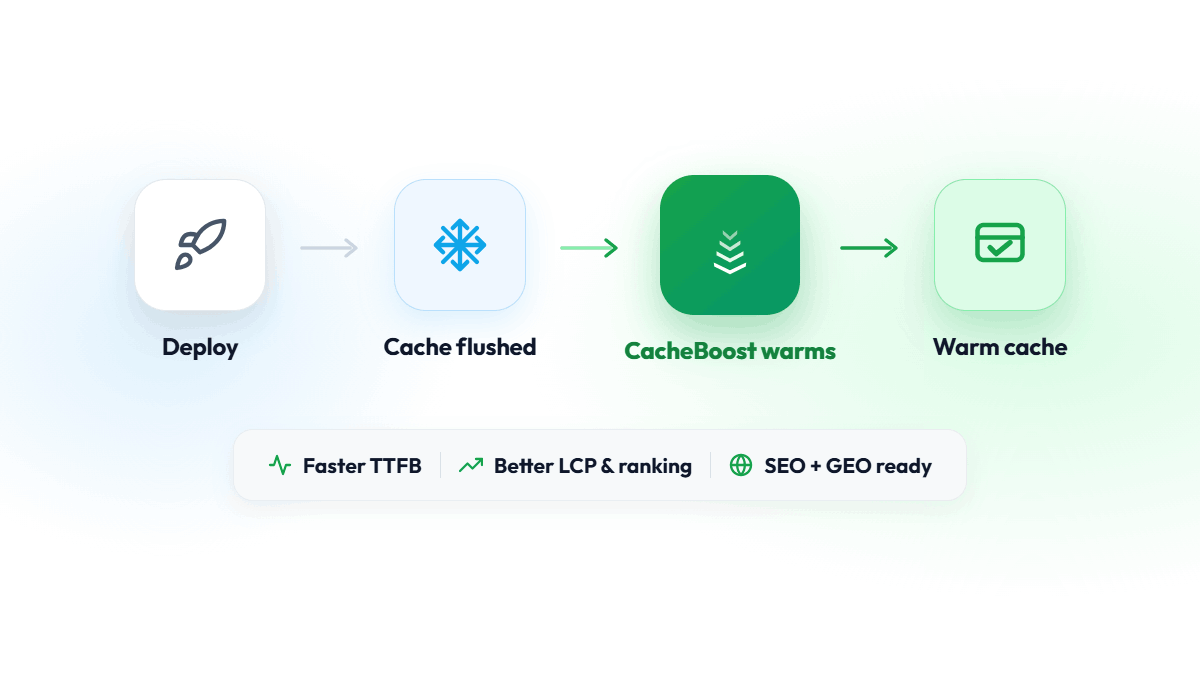
- Warm after every flush. That's the only way the post-purge window stops being a hole.
- Track cache hit ratio per crawler. Cloudflare's
cacheStatusdimension is the authoritative hit/miss source; grouped by bot, it tells you whether AI crawlers are systematically landing on a MISS. CacheBoost's crawler analytics does this for you once you connect a Cloudflare API token: it polls the GraphQL Analytics API hourly and charts SEO and GEO crawlers separately, so you can see the post-purge dip without building the pipeline yourself.
Related reading: Why Cache Warming Matters for SEO and GEO and New: Track How SEO and AI Crawlers Hit Your Cache.